AdsCrawl Screenshot API opens a URL in a browser and returns a PNG image through POST /screenshot. Use fullPage for a full-page capture or selector for the first matching element. The successful response is binary image data, so save it as a file rather than parsing it as JSON.
Web Scraping API: Extract named text or numeric fields when your application needs data as well as an image.
Playwright Cloud Browser: Use a Playwright script when you need to navigate, fill a form or click before taking a screenshot.
Quick answers
How should I combine web scraping and screenshots in a headless browser architecture?
Use one Remote CDP session when extracted data and a screenshot must describe the same browser state. Navigate, wait for the required content, read the fields and capture the page before cleanup. For independent URL captures, POST /screenshot returns PNG and POST /spa-extract returns named fields; separate requests are separate page loads and may observe different content.
For simple captures, queue one URL per screenshot request and save the successful PNG response.
For login, clicks or a shared page state, use Playwright or Puppeteer in one CDP session and wait for the required element before extraction and capture.
Store the URL, capture time and output together; delete the session after saving both results.
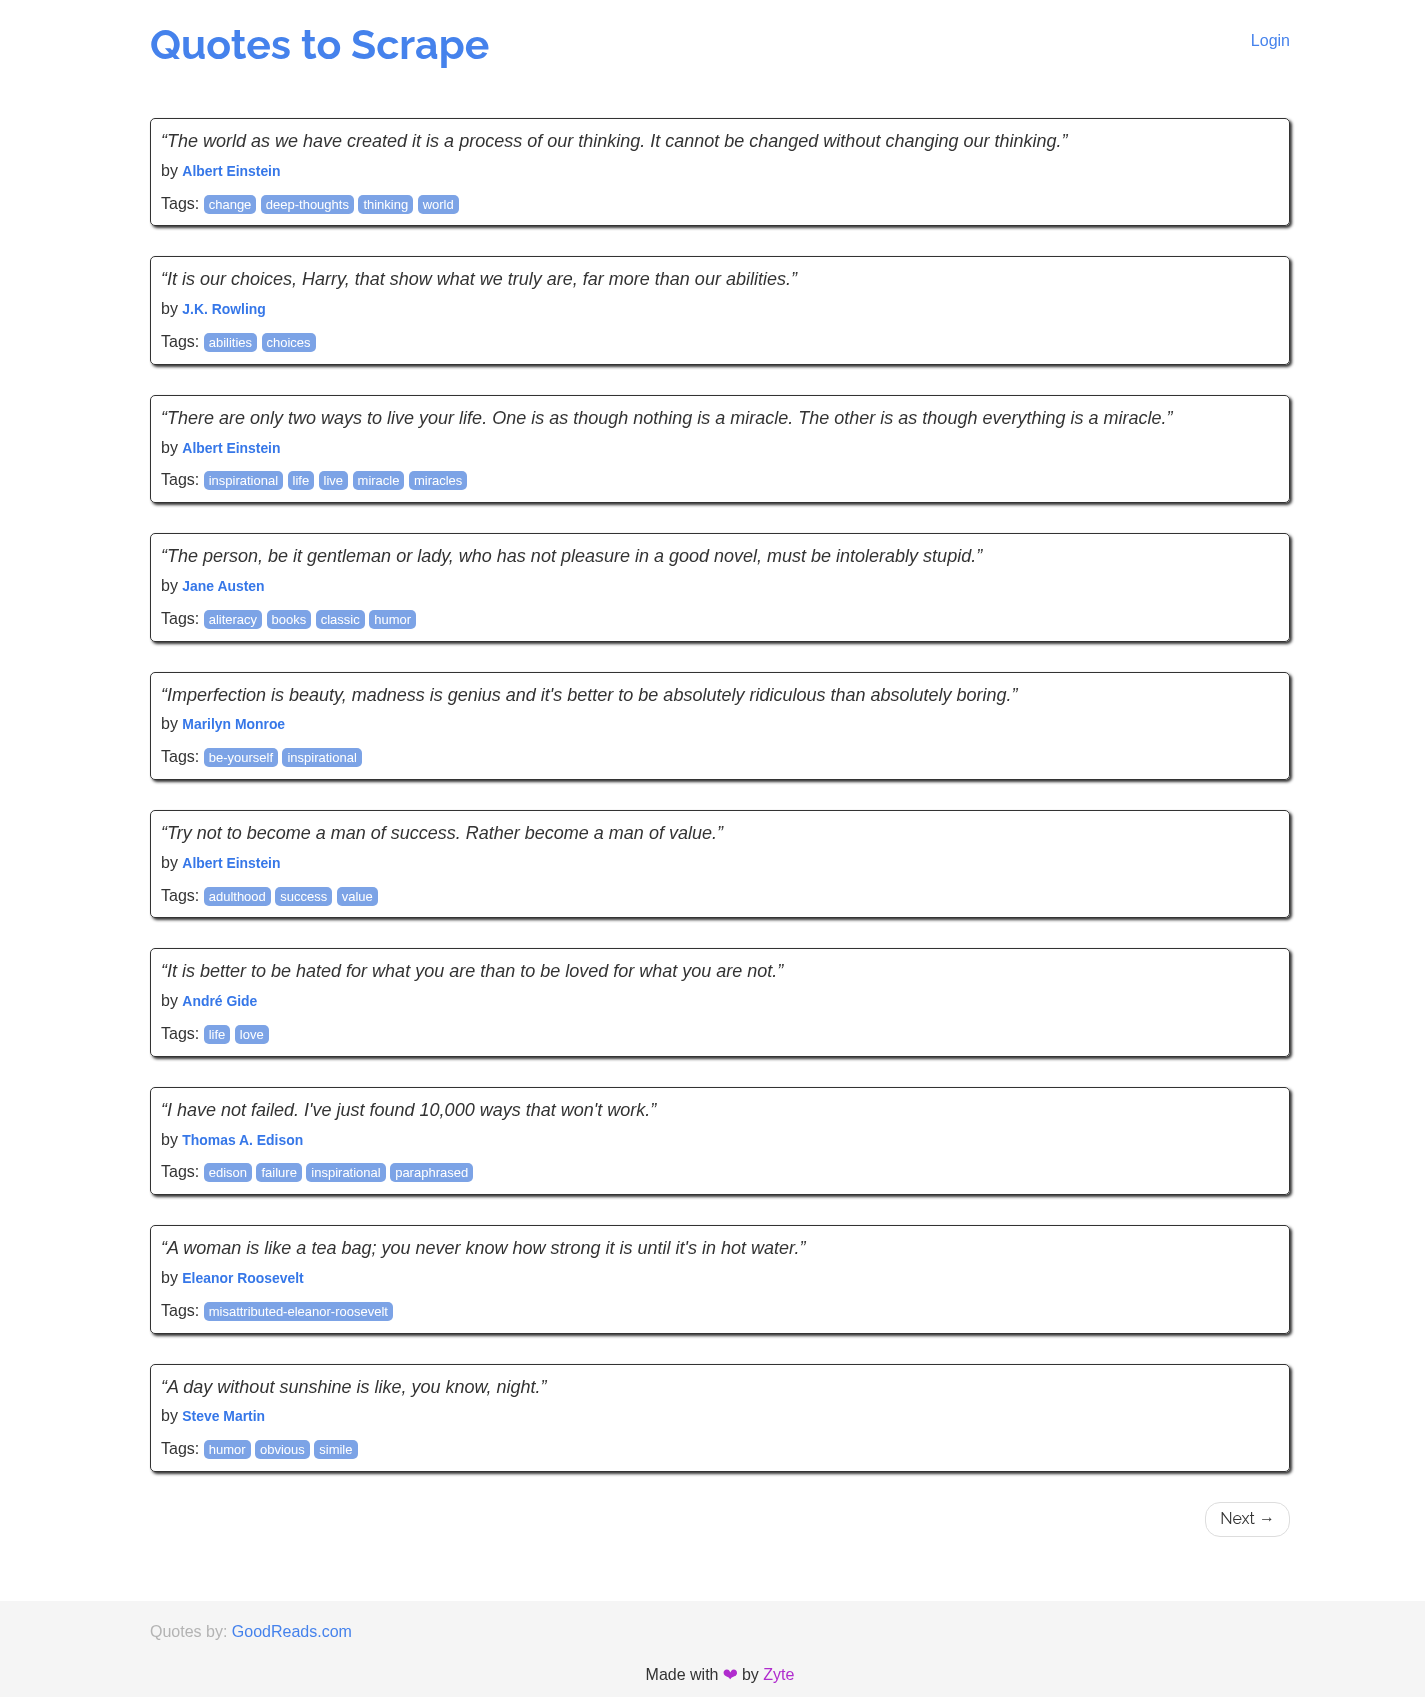
A full-page capture of the JavaScript-rendered Quotes to Scrape page. Scroll through the preview or download the original PNG to inspect the text, layout and page bottom.
A recorded public-page example. Results reflect the page at capture time and can change with the target website, loading conditions and request settings.
02 / USE CASES
Where it fits
01
Preview complete pages
Generate full-page images for review tools and internal website previews. Keep the target URL with the image so reviewers can identify its source.
02
Focus on a component
Capture a chart, card or other element with a precise CSS selector. The endpoint captures the first matching element.
03
Retain visual context
Store screenshots alongside monitoring results or research notes. A capture records the rendered page at request time; it is not a guarantee of future appearance.
03 / QUICKSTART
Start with one complete workflow
Set a server-side API key and choose the target URL.
Choose fullPage for the whole page or selector for one element.
Send POST /screenshot with an appropriate documented wait condition.
Check the response status and save the successful binary response as screenshot.png.
Requires Bash and cURL. Set the ADSCRAWL_API_KEY environment variable on your server first.
A useful website screenshot depends on the area you capture and the state of the page. Set a consistent viewport, choose the capture area, and inspect the PNG before using it in a report or comparison.
Capture the full page
Set fullPage to true and omit selector to capture the page beyond the viewport. Set viewport width and height explicitly when you want repeatable page layout across requests.
Provide a CSS selector for the first matching element. selector takes precedence over fullPage, including when fullPage is true. A selector that does not match returns HTTP 422.
Use a Playwright browser workflow when you need to navigate, fill a form or click through several steps before taking a screenshot. Your script can wait for the application state it needs.
Choose waitUntil for the target page. networkidle can time out on long-polling pages; a completed navigation does not prove every dynamic widget is ready.
Save a successful response as PNG bytes, for example with cURL --output screenshot.png. Check the HTTP status before treating the response as an image.
Open the resulting image and verify the capture area, text and loaded content. Keep viewport settings consistent when comparing captures over time.
04 / LIMITS & BILLING
Know the boundaries
Sign up with 500 one-time credits. Hobby is $9/month, Starter $49/month and Pro $199/month. Launching a persistent Cloud Browser requires a paid plan.
A failed response may contain error text instead of PNG bytes. Check the HTTP status before saving the output as an image.
Lazy-loaded images and delayed widgets may require additional supported wait options. A load event does not guarantee all content is ready.
Use a specific selector and confirm the element exists. The endpoint does not capture every matching element in one selector screenshot.
Captures consume account credits and use browser capacity. Review pricing before scheduling frequent screenshots.
For multiple URLs, orchestrate separate POST /screenshot requests in your application, sequentially or within your account concurrency allowance. This example is one URL per request, not a batch endpoint.
waitUntil supports domcontentloaded, load (default) and networkidle. networkidle waits for 500 ms without network connections and can time out on active pages. timeoutMs accepts positive integers up to 3,600,000; invalid values use the server default.
An unmatched selector returns HTTP 422 with CONTENT_SELECTOR_NOT_FOUND; a successful response is binary image/png.
Keep API keys on the server. For HTTP 402 check your balance; for 429 reduce concurrency and retry with backoff.
05 / FAQ
Common questions
Can I screenshot only a chart?
Yes. Supply a CSS selector for the chart container. The capture uses the first matching element.
Can I get a full-page screenshot and extracted text in one API call?
No. POST /screenshot returns PNG only. For text, make a separate POST /html or POST /spa-extract request. To capture both from the same page state, use Playwright or Puppeteer in one Remote CDP session: wait for the content, read the text and take the screenshot before cleanup. That is a multi-step browser workflow, not one combined API response or OCR.
Why is some dynamic content absent?
The screenshot reflects the page when capture occurs. Check the target site's loading behavior and choose supported wait settings that match it.
ADSCRAWL PRODUCTS
Related workflows
Choose the next workflow by the output, client or browser state your task needs.