AdsCrawl Web to Markdown API converts a page URL into readable article content using POST /html with contentMode set to markdown. The browser renders the page before main-text extraction. Use the returned Markdown for research, document processing and LLM workflows that need article text rather than the complete page markup.
Web Scraping API: Use explicit field definitions when you need exact product values, table cells or structured records.
Browser for AI Agents: Add browser actions when an agent must interact with a page instead of only reading its article content.
Can an article extraction API work with modern web apps?
Yes, when the rendered page contains readable article content. AdsCrawl POST /html with contentMode set to markdown renders the page and extracts its main text. It is not a complete export of an interactive app: dashboards, tables or content behind additional actions may need named-field extraction or a CDP workflow instead.
Request Markdown for one representative article and inspect the returned text against the rendered page.
Check the required paragraphs and headings; do not assume navigation, widgets or every table will be included.
Preserve the source URL and retrieval time with the text before chunking, indexing or summarizing it.
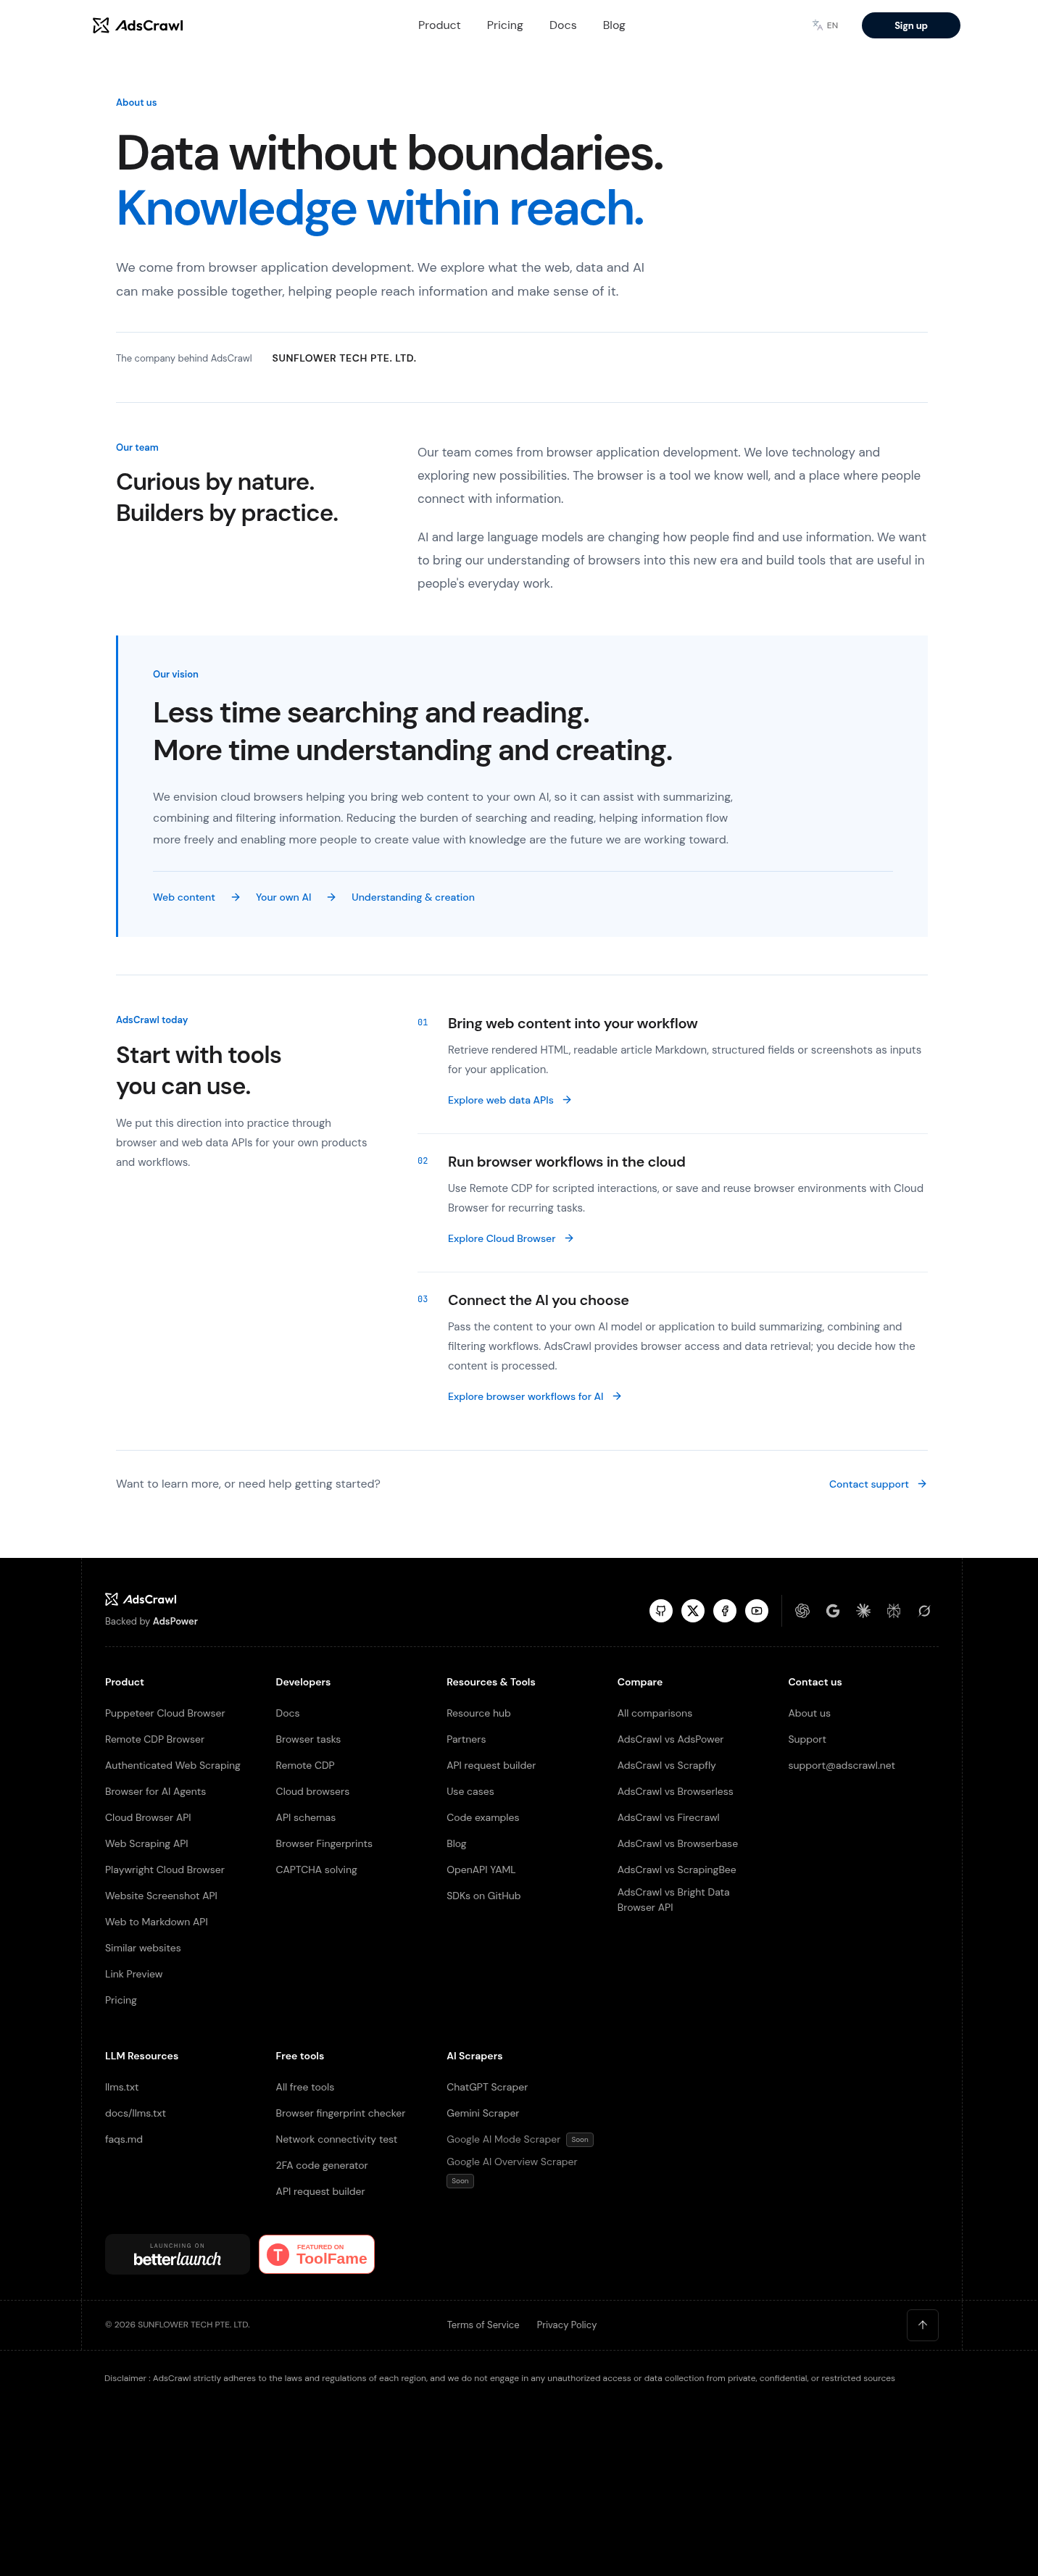
This request extracts the main content of AdsCrawl’s About page. Inspect the headings, paragraphs and links in the saved response before using them in a text pipeline.
# About us | AdsCrawl

About us

## Data without boundaries.
Knowledge within reach.

We come from browser application development. We explore what the web, data and AI can make possible together, helping people reach information and make sense of it.

The company behind AdsCrawl**SUNFLOWER TECH PTE. LTD.**

Our team

## Curious by nature. Builders by practice.

Our team comes from browser application development. We love technology and exploring new possibilities. The browser is a tool we know well, and a place where people connect with information.

AI and large language models are changing how people find and use information. We want to bring our understanding of browsers into this new era and build tools that are useful in people's everyday work.

Our vision

## Less time searching and reading. More time understanding and creating.

We envision cloud browsers helping you bring web content to your own AI, so it can assist with summarizing, combining and filtering information. Reducing the burden of searching and reading, helping information flow more freely and enabling more people to create value with knowledge are the future we are working toward.

1.  Web content
2.  Your own AI
3.  Understanding & creation

AdsCrawl today

## Start with tools you can use.

We put this direction into practice through browser and web data APIs for your own products and workflows.

1.  ### Bring web content into your workflow

    Retrieve rendered HTML, readable article Markdown, structured fields or screenshots as inputs for your application.

    [Explore web data APIs](https://www.adscrawl.net/web-scraping-api/)

2.  ### Run browser workflows in the cloud

    Use Remote CDP for scripted interactions, or save and reuse browser environments with Cloud Browser for recurring tasks.

    [Explore Cloud Browser](https://www.adscrawl.net/cloud-browser-api/)

3.  ### Connect the AI you choose

    Pass the content to your own AI model or application to build summarizing, combining and filtering workflows. AdsCrawl provides browser access and data retrieval; you decide how the content is processed.

    [Explore browser workflows for AI](https://www.adscrawl.net/browser-for-ai-agents/)
What to check
Compare the main sections and links with the source page. The request targets main, so the surrounding navigation and footer are outside the extraction scope.
A recorded public-page example. Results reflect the page at capture time and can change with the target website, loading conditions and request settings.
02 / USE CASES
Where it fits
01
Prepare text for retrieval
Use readable content as input to your own chunking and retrieval pipeline. Store the source URL alongside it so later answers can point back to the page.
02
Collect research material
Save article content in a portable text format for internal reference. Review the result before using it in summaries or reports.
03
Choose the right representation
Request Markdown for readable content, HTML for rendered markup, or named extraction fields when you need precise values. Avoid parsing a format your task does not need.
03 / QUICKSTART
Start with one complete workflow
Create a server-side API key and choose the page URL.
Send POST /html with contentMode set to markdown.
Check the response status and save the text as page.md.
Review extracted content and preserve its source URL in your downstream workflow.
Requires Bash and cURL. Set the ADSCRAWL_API_KEY environment variable on your server first.
A URL-to-Markdown request gives your application readable article text. Choose the extraction mode, review the returned content, then attach source information before chunking or indexing it.
Extract an article as Markdown
Send POST /html with contentMode set to markdown. A selector can scope article extraction to the first matching element. The response is Markdown text; save or read it as text in your application.
For product attributes, prices or other named values, define fields with the Web Scraping API. Article extraction selects readable content and may omit navigation, controls and other surrounding page elements.
Illustrative output (not an actual request result)
This authored example shows the kind of Markdown a text pipeline can consume. Actual content and formatting depend on the source page.
# Collection guide

Bring your order reference when collecting a parcel.

## Opening hours

- Monday to Friday
- 09:00 to 17:00
Check your result
Compare the returned text with the source article before indexing. Check that the main sections your application needs are present.
Handle READABILITY_CONTENT_NOT_FOUND when a page has no extractable article. Use HTML or named-field extraction when those outputs better fit the page.
Store the source URL and retrieval time alongside the Markdown in your application, then use them when displaying citations or refreshing documents.
04 / LIMITS & BILLING
Know the boundaries
Sign up with 500 one-time credits. Hobby is $9/month, Starter $49/month and Pro $199/month. Launching a persistent Cloud Browser requires a paid plan.
Readable-content extraction is not a lossless page copy. Navigation, interactive widgets and layout-specific elements may be omitted.
Markdown conversion does not verify the source's facts or grant permission to republish its content.
Dynamic content still depends on page loading and supported wait settings. Check the output rather than assuming every section was captured.
Requests consume credits and are subject to account limits. This endpoint does not supply a complete retrieval or embedding pipeline.
Keep API keys on the server. For HTTP 402 check your balance; for 429 reduce concurrency and retry with backoff.
05 / FAQ
Common questions
Is there a separate /markdown endpoint?
No. Use POST /html with contentMode set to markdown. The output mode selects Markdown within the existing endpoint.
Does Markdown include every element?
No. It is intended for readable content, not a complete representation of the visual layout or every interactive element.
Should I use this for exact product fields?
If you need a fixed set of named values, use the Web Scraping API with explicit field definitions. Markdown is useful when your workflow needs readable text.
ADSCRAWL PRODUCTS
Related workflows
Choose the next workflow by the output, client or browser state your task needs.