AdsCrawl Web Scraping API extracts specified fields from browser-rendered websites through POST /spa-extract. Define fields using DOM selectors or supported network response sources. When you need rendered markup or readable page content instead, use POST /html with the appropriate output mode.
Web to Markdown API: Use readable article text when your pipeline needs paragraphs rather than a fixed set of named fields.
Remote CDP Browser: Keep navigation, clicks and extraction in one scripted browser session for an interactive workflow.
Which scraping API should I use for JavaScript-heavy sites?
Use browser-rendered field extraction when the values you need appear after JavaScript runs. With AdsCrawl, POST /spa-extract can wait for a selector and return named DOM or supported network fields. For multi-step navigation, use Remote CDP. Judge the result by complete, valid fields on your target pages, not just an HTTP 200 response.
Identify the required fields and a readiness selector; set waitFor.selector and define fields in the extraction request.
Validate data, missingFields and field types before saving a record. A missing required field can return HTTP 422.
Test a representative batch, recording retries and cost per valid record; put scheduling and concurrency control in your application.
{
  "data": {
    "author": "Albert Einstein",
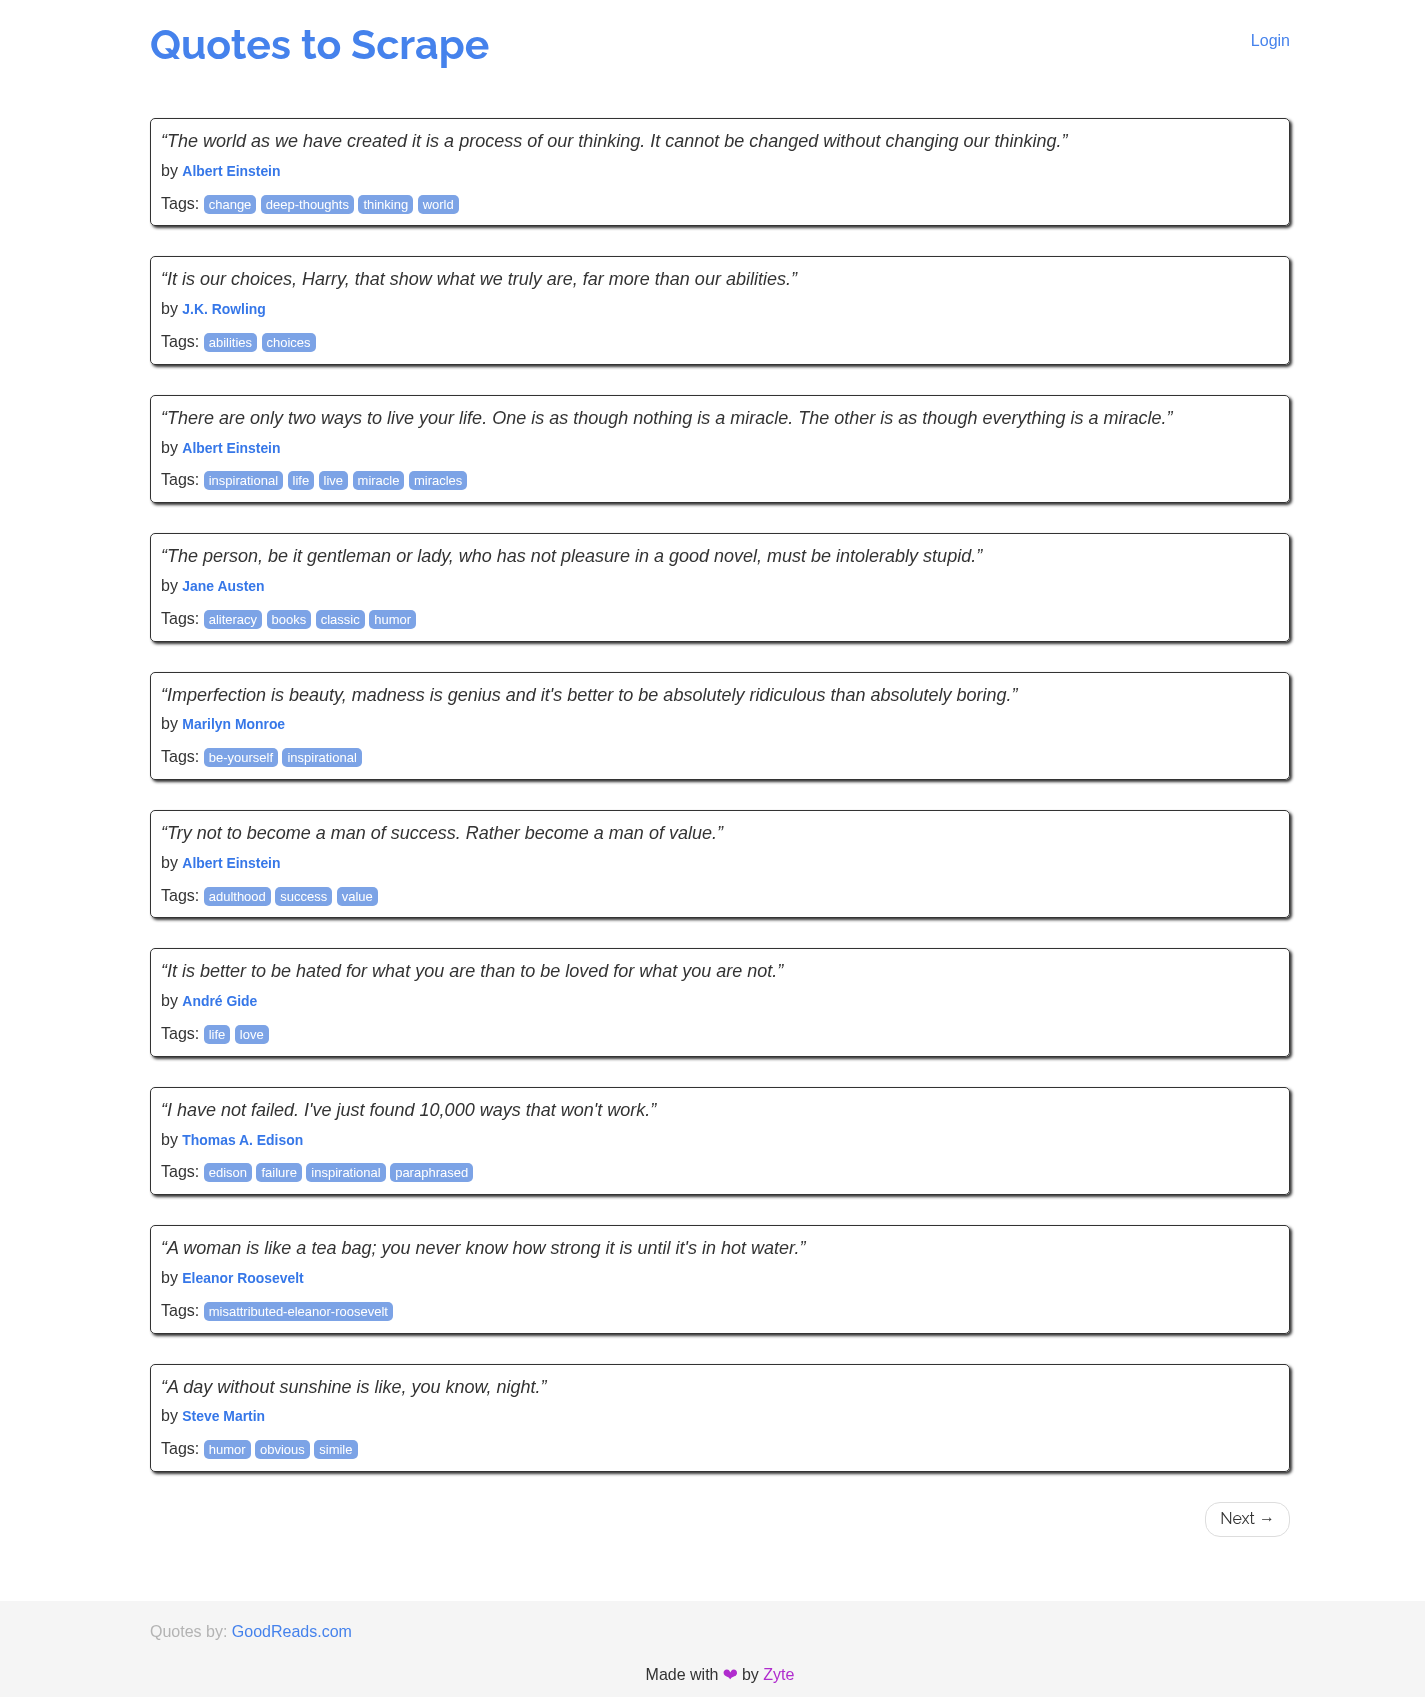
    "quote": "“The world as we have created it is a process of our thinking. It cannot be changed without changing our thinking.”"
  },
  "missingFields": [],
  "mode": "extract",
  "page": {
    "url": "https://quotes.toscrape.com/js/",
    "title": "Quotes to Scrape"
  }
}
What to check
Compare data.quote and data.author with the first quote on the source page. An empty missingFields list means both requested fields were found in this run.
A recorded public-page example. Results reflect the page at capture time and can change with the target website, loading conditions and request settings.
VALIDATE ONE COMPLETE TASK
Get verifiable JSON from a dynamic page
01
Wait for the target element
Call POST /spa-extract for https://quotes.toscrape.com/js/. Set waitFor.selector to .quote .text so field extraction waits for rendered content.
02
Define and validate fields
Use .quote .text for quote and .quote .author for author, both required with parse: string. Check a non-empty data.quote, data.author equal to Albert Einstein and an empty missingFields list.
03
Exercise the failure branch
Change a required field selector to a missing element in your test workflow and check that the result is rejected or handled as missing data. HTTP 200 alone does not establish that your data requirements were met.
The reference was captured on 2026-11-04 in one AdsCrawl run. It does not establish success rates, performance or cost across other sites. Download the request and result, then repeat the checks on your target page.
Define CSS selectors for the names, headings or values your application needs. Give each field a stable name so downstream code does not depend on the complete page markup.
02
Read dynamic data
Use supported network fields when the page retrieves JSON while loading. Consult the API reference for matching and extraction rules.
03
Check completeness
Inspect missingFields alongside returned data. Detect changed selectors and incomplete loads before storing results in a monitoring or research pipeline.
03 / QUICKSTART
Start with one complete workflow
Create an API key and store it in a server-side environment variable.
Inspect your target page and identify a selector for each required field.
Send POST /spa-extract with mode set to extract and the fields object.
Check the returned values and missingFields before using the result.
Requires Bash, cURL and jq. Set the ADSCRAWL_API_KEY environment variable on your server first.
This optional-field fixture must fail the Quickstart's jq check. Marking the field required instead can return HTTP 422 with SPA_REQUIRED_FIELDS_MISSING.
A target-site redesign can invalidate selectors. Validate the response rather than assuming every request returns every field.
Page readiness depends on the target site. Choose wait conditions within the endpoint's supported limits.
Use Remote CDP for multi-step navigation, clicks and forms. Field extraction is not a replacement for a browser script.
Requests use account credits and are subject to concurrency limits. Check your plan before scheduling a batch.
Keep API keys on the server. For HTTP 402 check your balance; for 429 reduce concurrency and retry with backoff.
05 / FAQ
Common questions
Should I use /html or /spa-extract?
Use /html for rendered HTML or readable article content. Use /spa-extract when you need a specified set of DOM or supported network fields.
What happens when a selector does not match?
Inspect missingFields and the returned data. Check the current selector and wait settings, then update your field definition if the target site's structure has changed.
Does a successful response mean my data is correct?
No. Validate required fields, types and any business rules before storing the result. Rendering and extraction do not establish that the source's claims are accurate.
ADSCRAWL PRODUCTS
Related workflows
Choose the next workflow by the output, client or browser state your task needs.